Newsletter
Five minutes. What happened, and what to do about it.
The US government backs OpenAI in the New York Times copyright case
 The Verge· 2 Sep
The US administration told the court in the New York Times case against OpenAI and Microsoft that training models on copyrighted text is fair use. The filing decides nothing, but the case could set precedent. If you publish anything, it bears on whether models may train on it. If you use models, it could affect what they cost.
- If you publish guides, prices or data, decide whether you mind it being trained on. Terms pages are where that is stated.
- Keep a source for every number an AI tool puts in front of a customer.
Source: The Verge. This is our short summary of their reporting. The commentary in it and the things to do are SeedFoundry's opinion. Picture from the source, unless it is our own graphic. How we source and credit
 Google
Gemini 3.8 Flash nears pricier models on agent work, at the cheap-tier price
 TechCrunch
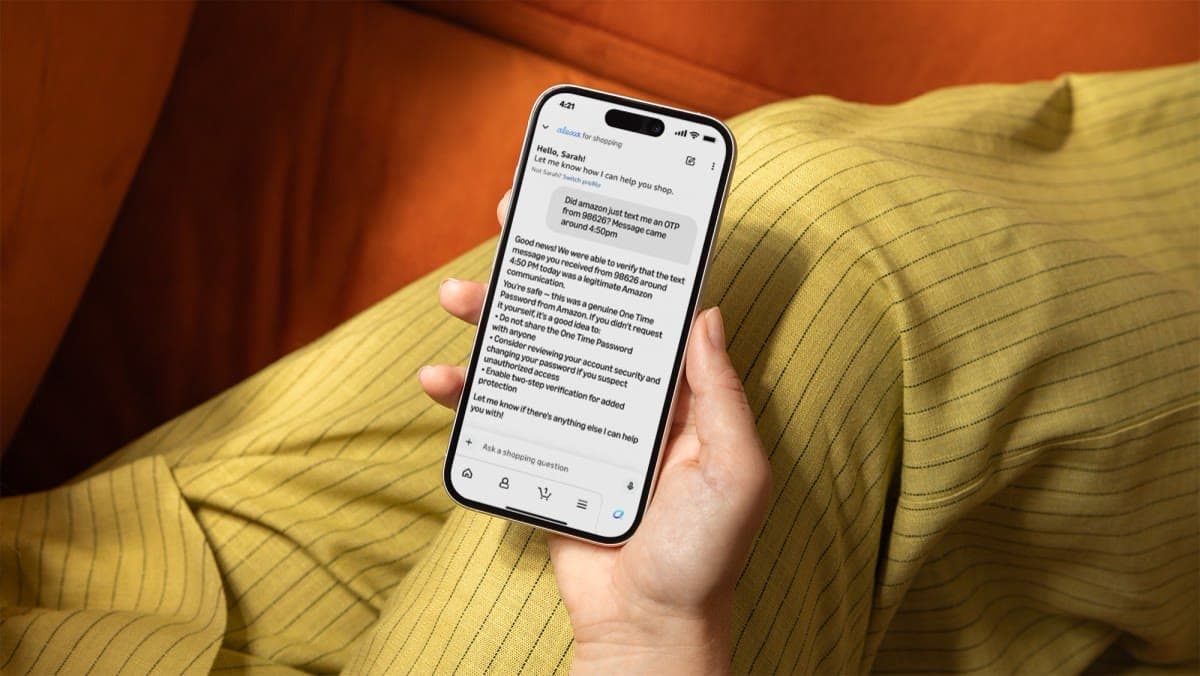
Amazon's shopping AI will now tell you if that Amazon message is a scam
These are short summaries of other people's reporting, with our own commentary. Each story names its source and links to the original. How we source and credit